Hands-on DDD and Event Sourcing [3/6]: Domain events, Event Sourcing and CQRS
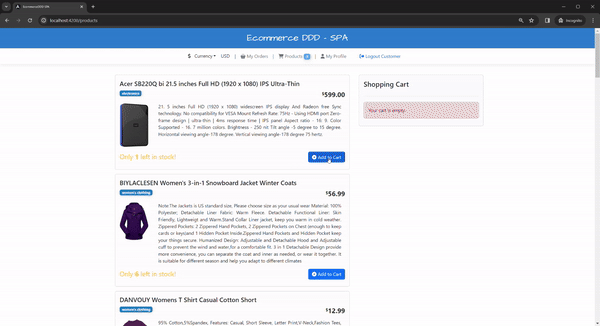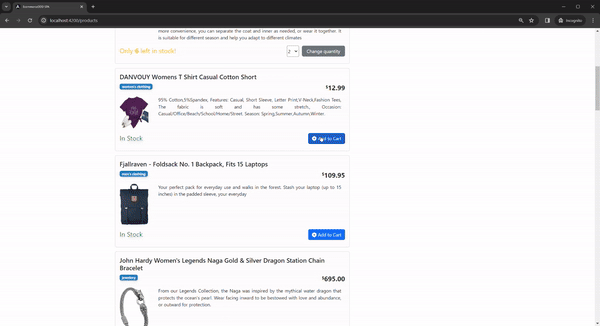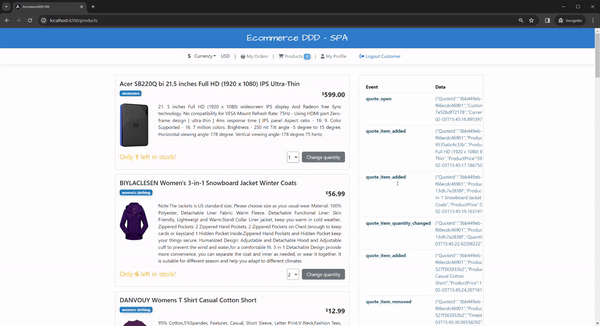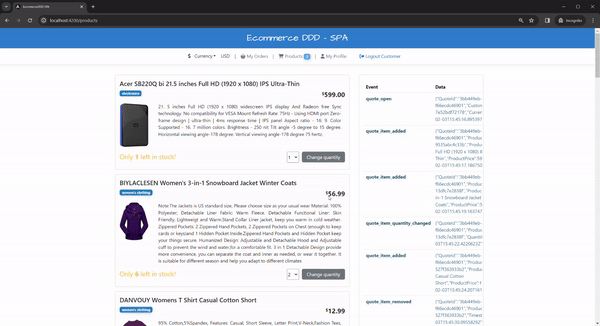
In the previous post, I covered a bit more about bounded contexts and some of the building blocks of the implementation. Now, let’s extend the implementation to domain events.
- Part 1 - EcommerceDDD overview
- Part 2 - Strategic and Tactical Design
- Part 3 - Domain events, Event Sourcing and CQRS
- Part 4 - Persisting Events and implementing Saga
- Part 5 - Wrapping up backend infrastructure
- Part 6 - Angular SPA and API consumption
- EcommerceDDD++: Streamlining API Client Generation with Kiota and Koalesce
Domain Events
Before we jump into Event Sourcing, let’s make a clear distinction: there are many types of events in software architecture, but not all events are domain events, and domain events don’t necessarily imply Event Sourcing.
A domain event represents an immutable fact that has already occurred in the domain, the result of a business behavior. Ideally, your aggregates should expose explicit behaviors (rather than being anemic), and from those behaviors, domain events are born. Once again, ubiquitous language plays a key role in how these events are named and understood.
Domain events are always context-bound, and their meaning holds only within the bounded context where they originated.
💡 When naming events, look at the context and pick a name that carries real meaning, using the [Noun][PastTenseVerb] combination (e.g. CustomerRegistered, OrderShipped).
What about Integration events?
Although they look similar, Domain and Integration events serve different purposes and operate at different scopes.
- Domain Events: Trigger reactions within the same bounded context, and are most often dispatched in-process. What makes an event a domain event is the scope of its meaning, not the transport it happens to travel on.
- Integration Events: Trigger reactions across different bounded contexts or external systems, and are typically handled asynchronously using a messaging infrastructure. Since they fan out across service boundaries, they require a higher level of decoupling and have to tolerate unexpected response times. This will be clear when we advance to the complete order processing flow.
To stream integration events, you’ll usually use a message broker. There are many options available, and for this project, I’m using Kafka, although I’ve also had great experiences with RabbitMQ. We’ll cover the implementation when tackling the infrastructure.
Event Sourcing
In short, Event Sourcing is an architectural pattern in which state changes are represented as a sequence of events, and these events serve as the source of truth.
Logging events is not a new concept in software, but Greg Young shaped the technique into the form we call Event Sourcing nowadays:
- Events are chronologically persisted in what’s called an
Event Store. - For this to work consistently, the store has to be append-only: the events themselves are immutable facts, so they are always appended, but never changed or deleted.
Event Sourcing also allows us to shift from the conventional approach, which was storing, changing and fetching the last state of an object, to reading the object’s event history and then rehydrating it to its latest state. Also, an event store is great at appending events and loading a single aggregate, but poor at answering queries, so reads are fetched from separate projections. That split between write and read models is exactly what CQRS describes, which is why the two pair so naturally.
Event Sourcing is technology-agnostic, with some good players in the market, such as KurrentDB (formerly EventStoreDB). Since I’m using PostgreSQL as a document database, Marten was the natural choice.
With Event Sourcing:
- Each state transition in an aggregate is captured as a domain event.
- Events are appended chronologically in an event store, instead of overwriting the current object’s state.
- The system rebuilds aggregate state by
rehydratingit from its stream of past events.
Why use Event Sourcing?
This approach gives you a few things for free:
- The object-relational impedance mismatch stops being a problem on the write side. You store data as it was intended, event-based and serialized.
- You get a natural audit trail. The complete event history reveals how and why the current state exists that way.
- You get a natural fit for CQRS, since queries are served by projections instead of the event stream, and each side can scale on its own.
Embedded complexity
Not all that glitters is gold. This shift in approach carries a fairly steep learning curve, especially if you use an in-house implementation, which is great for learning but rarely worth it in a corporate environment. There are frameworks that absorb most of that complexity for you, and I recommend leaning on one, like I did with Marten here. More on that in Part 4.
Some aspects to consider when using Event Sourcing are:
Concurrency and optimistic locking, for when multiple users edit the same record at once, so a write based on a stale version of the stream is rejected instead of silently overwriting another one. There’s a very nice article that covers it in depth, and I won’t try to do it better here.Schema evolution, for when event structures change over time, usually handled throughupcasting, by translating events written in an older shape into the current one as they are read, so old streams keep replaying without crashing.Event versioning, for when a change to an event’s shape is breaking. You introduce a new version of the event instead of editing the old ones, so consumers and upcasters know which shape they are dealing with.Performance tuning of long event streams and projections, for when a stream grows to thousands of events and full replay gets slow. Snapshots (a periodically stored state you replay forward from) cap that cost on the write side, while read models stay current by applying each new event as it arrives.
Hydrating Aggregates with Domain Events
I want to focus on the technique and not on Marten, although things get mixed up because we need to follow Marten’s convention so the framework can do its job. I’ll cover how Marten persists it in the next post, but for now, let’s walk through a simple example using the Customer aggregate root that lives at the EcommerceDDD.CustomerManagement bounded context.
After all the domain invariants are validated, the domain object is finally ready to be constructed, and the constructor calls the AppendEvent and the Apply methods in sequence:
1
2
AppendEvent(@event);
Apply(@event);
- AppendEvent is defined in the AggregateRoot base class, and it adds the event to the uncommitted events queue of
IDomainEvent. - Apply is not declared in the base class. It’s a set of overloads on the aggregate itself, one per event type, picked by the argument type. That’s the convention Marten relies on to rehydrate the aggregate, and each applied event mutates a corresponding part of it.
Take, for example, the act of updating an existing customer. Instead of directly modifying customer fields like we would usually do in a non-event-sourced architecture, the code would execute an action on the customer (the customer.UpdateInformation method), which makes it emit a CustomerUpdated domain event.
The event is appended to the uncommitted events queue through AppendEvent, then applied through Apply:
And with Customer now mutated (its data was updated, in memory), we’re ready to persist the event into the event store, through the IEventStoreRepository<Customer> in the UpdateCustomerInformationHandler.
The sequence here is:
- The
UpdateCustomerInformationHandlerfetches the stream and Marten rehydratesCustomerby replaying its events, while staging an optimistic concurrency check for the commit. customer.UpdateInformation(customerData)validates the invariants and emits theCustomerUpdateddomain event, appending it to the uncommitted events queue and applying it to mutate the in-memory aggregate.AppendEventsAndCommitAsyncdrains that queue into the stream and commits it into the event store, bumping the stream version.
Notice that nothing overwrote the customer like we would traditionally do. The last state of the customer is the result of applying every event in its stream (CustomerRegistered followed by each CustomerUpdated), and the next fetch will replay them all.
⚠️ Important: in this project, in-process domain event handlers only run after the aggregate is successfully persisted, so nothing reacts to a fact that may still be rolled back.
CQRS: Command Query Responsibility Segregation
CQRS is an architectural pattern that is often mentioned alongside Event Sourcing, and for good reason. They pair perfectly!
Commandsexpress user intents and actions. Commands will be the triggers to change the state of our aggregate and emit events on the write side.Queriesretrieve the current state from the read model. CQRS itself doesn’t dictate how that model is stored, but once you pair it with Event Sourcing, a materialized projection becomes the natural fit, which is the route this project takes.
This separation allows your write model to focus purely on domain logic and emitting events, while your read model is optimized for performance and user experience.
Still on the customer example, under EcommerceDDD.CustomerManagement.Application, namespaces like RegisteringCustomer and UpdatingCustomerInformation hold the commands and handlers to register and to update a customer.
UpdateCustomerInformation command:
UpdateCustomerInformationHandler:
The ones in namespaces starting with Getting, on the other hand, hold queries that retrieve data related to the customer.
GetCustomerDetailsById query:
GetCustomerDetailsByIdHandler:
We’re not diving deep into database persistence yet, but at this point it must be clear that commands write events into the write model (the event store), and queries read from a read model. CQRS does not mandate separate databases, and here both live in the same PostgreSQL instance under different schemas. With Event Sourcing, though, a separate read model is a must, since we won’t query the event store directly, but projections built from it. In the next post, that will make more sense when I cover Projections.
💡 Update: The commands and queries here are now dispatched through Wolverine’s IMessageBus, which discovers handlers like UpdateCustomerInformationHandler and GetCustomerDetailsByIdHandler by naming convention. The initial versions of the project used MediatR, then I moved to a self-made implementation, which I removed once it became redundant after I started using Wolverine. I kept the ICommand and IQuery<T> interfaces as markers, only for shaping the API responses in CustomControllerBase.
What’s next
In the next post, I’ll show how Marten persists events into PostgreSQL and keeps projections up to date. I’ll also cover how the Saga pattern coordinates the order workflow across services.
Links worth checking
- Aggregates, Events, Repositories with Marten
- CQRS pattern
- Event Streaming is not Event Sourcing! by Oskar Dudycz
- Optimistic concurrency for pessimistic times
- Domain events
- Ubiquitous language
- Bounded context
- Event Upcasting