Hands-on DDD and Event Sourcing [4/6]: Persisting Events and implementing Saga
In the previous post, I talked about Domain events, Event Sourcing and CQRS. Now let’s look at how to persist, project, and read events using Marten, and then how a saga orchestrates them into a business workflow.
- Part 1 - EcommerceDDD overview
- Part 2 - Strategic and Tactical Design
- Part 3 - Domain events, Event Sourcing and CQRS
- Part 4 - Persisting Events and implementing Saga
- Part 5 - Wrapping up backend infrastructure
- Part 6 - Angular SPA and API consumption
- EcommerceDDD++: Streamlining API Client Generation with Kiota and Koalesce
What is Marten?
Marten is a .NET library that allows developers to use the Postgresql database as both a document database and a fully-featured event store – with the document features serving as the out-of-the-box mechanism for projected “read side” views of your events.
As their website describes, it was built to replace RavenDB inside a very large web application that was suffering stability and performance issues.
While studying event sourcing, I looked for an out-of-the-box implementation so I could easily revamp this project from a relational database to an event-sourced one. The library is aligned with .NET Core Support Lifecycle to determine platform compatibility, and they seem to be constantly improving it. You can check their project on GitHub and their nice documentation at Marten.io. I followed their documentation to use what I needed for this project.
PostgreSQL as document database
PostgreSQL is a powerful, open source object-relational database system with over 30 years of active development that has earned it a strong reputation for reliability, feature robustness, and performance.
As I mentioned before, we need to persist serialized events in an event store, and the perfect place for it is a document-oriented database rather than a relational one. Using PostgreSQL is a viable option, especially considering its support for JSON. It was a perfect match for Marten.
Writing and Reading events
To ease writing and reading events with Marten, I opted for a pragmatic abstraction using the IEventStoreRepository, which you can find in the EcommerceDDD.Core project and implemented as MartenRepository under EcommerceDDD.Core.Infrastructure/Marten.
I don’t advocate generic repositories when designing aggregate roots, but this was a straightforward solution for persisting domain events. Still, there’s a constraint that ensures it works only for an aggregate root, which complies with the base class that contains a queue of uncommitted IDomainEvents, ready to be stored.
The repository implementation uses an abstraction called IDocumentSession, allowing us to use different flavors of what Marten calls a session.
💡 Notice how it resembles a Unit of Work / Entity Framework DbContext: it holds pending changes and writes them in one transaction when a commit happens.
AppendEventsAndCommitAsync(TA aggregate)
First, this method uses the injected document session, and the underlying code does the following procedure:
- Gets all uncommitted events from the aggregate.
- Clears all uncommitted events from the aggregate.
- Appends the events to the stream (or starts a new one).
- Calculates the aggregate’s new version to return.
- Stages any integration events in the outbox.
- Calls SaveChangesAsync to commit the transaction.
At the end, the event stream contains the full, ordered history of the aggregate.
The method also takes an optional set of integration events to publish. When a command’s outcome has to reach another bounded context, the handler passes those events here rather than publishing them directly, and this is where the Outbox Pattern comes in.
Committing the aggregate’s events to PostgreSQL and publishing a message to a broker are two separate systems, and a crash between them leaves the two out of sync. That’s the dual-write problem, and I covered it in a dedicated post.
MartenRepository gets its outbox from IMartenOutbox, part of Wolverine’s Marten integration. The outgoing messages are staged in the same IDocumentSession as the events, so SaveChangesAsync commits both or neither, and nothing is sent anywhere until that transaction succeeds.
How the staged messages then travel to the broker is infrastructure, covered in Part 5.
FetchForWritingAsync(Guid id, int? version)
The method brings the aggregate from the event stream by Id, and stages an optimistic concurrency check for the commit that follows.
💡 There’s an optional version argument too. It’s not for loading an older state: it’s the version I expect the stream to be at, so if someone else wrote to it in the meantime, the commit fails instead of silently overwriting.
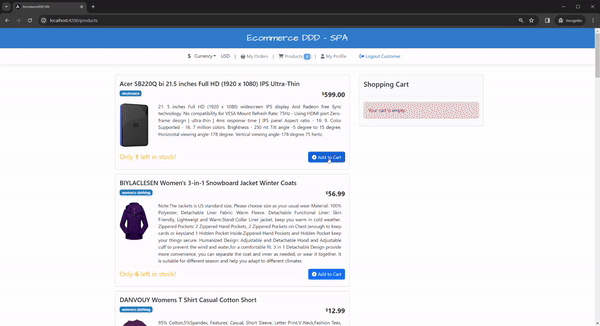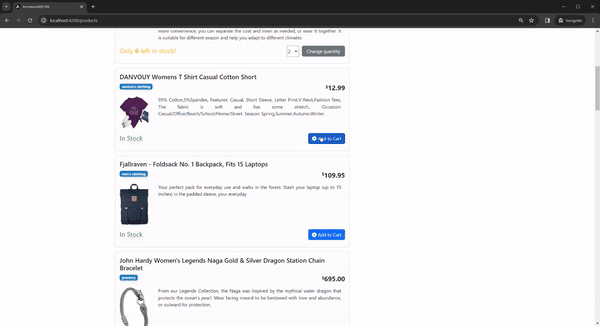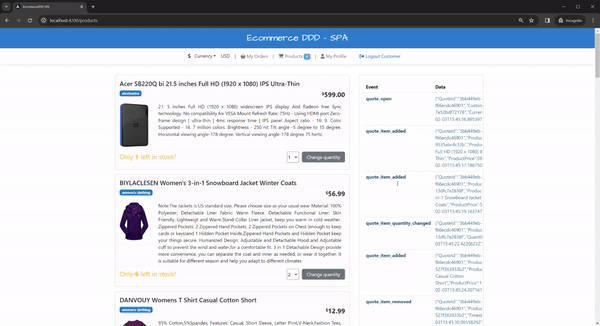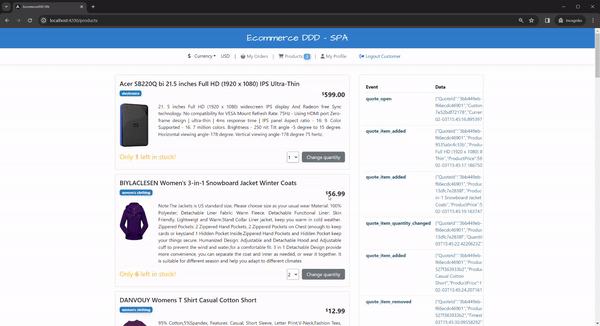
One interesting thing you can do is add breakpoints to all Apply methods of any aggregate, such as Quote, and then perform operations like adding or removing products or changing quantities. All these behaviors are commands that generate events and persist in the event stream. Lastly, when calling FetchForWritingAsync afterward for this aggregate again, you can track the Apply for each event in sequence and watch it rehydrating the aggregate.
The Event Store
Assuming you ran the app, it should have created one database for each microservice. I’m using pgAdmin as a GUI for managing PostgreSQL, and it’s already set as a Docker container available at localhost:8081:
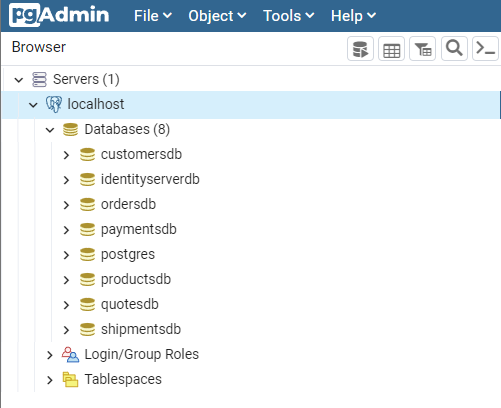
Still about Quotes for an order, let’s see how the data is handled under the hood. I mentioned earlier that every event-sourced service performs read and write operations separately using different schemas. When querying the quotes_write event store, we can see the sequence of every event added in chronological order:
1
2
SELECT * FROM quotes_write.mt_events
ORDER BY seq_id ASC

Notice the columns stream_id, which carries the aggregate id itself, the version, the data with the serialized event, the type name, and the dotnet_type describing the namespace and class name of the event. Cool, eh?
Projections
You’ve seen that we need to load the entire sequence of events to rehydrate the aggregate and get the current state. The example above shows at least six, but there’s no limit. Imagine a system in production handling thousands or hundreds of thousands of events per aggregate per user, and every time you query a particular object, you have to traverse that whole path to recreate it and reach the latest state, which is practically impossible to scale.
To solve this problem, you need to project only the latest states of the aggregate somewhere, more specifically, to the read database or table. That’s another feature I found handy with Marten: inline projections. It’s easy to set the projection of an event immediately as it’s stored. When the UI needs the API to query information, it reads it directly from the data projected in the read DB. The configuration is as simple as this:
Notice that the first projection QuoteDetailsProjection inherits from SingleStreamProjection for aggregating events by stream using pattern matching, where QuoteDetails is the actual projected object into the database table mt_doc_quotedetails.
1
2
SELECT * FROM quotes_read.mt_doc_quotedetails
ORDER BY id ASC

The second projection, QuoteEventHistoryTransform, is meant to be simpler, inheriting from the EventProjection base class to project the events of this aggregate, but transforming them into an object of the IEventHistory interface I created to standardize the history of all aggregates and to ease displaying it through the stored-events-viewer Angular component we will check in the last chapter of the series.
One of the beauties of using Event Sourcing is that we can shape the projected data as we need it, in many different forms for different visualizations, and place it in different places, without changing the original, immutable source of truth: the event store. Even if you destroy the read-only store containing the projections completely, you can reproject it to the exact last state over again, like rolling frames of a movie.
Write-side performance: projections solve the read problem, but rehydrating a very long event stream on the write side can also become costly. For those cases, Marten supports aggregate snapshots, a persisted point-in-time state of the aggregate, so that rehydration starts from the snapshot rather than replaying every event from the beginning.
Saga Pattern
Now that we have domain events persisted, able to rehydrate domain models and be projected as their final state, we need to make sense of the orchestration that makes them useful for business purposes. In this case, that’s an order fulfillment process spanning several bounded contexts, and just like commands and queries, events can have handlers reacting to them.
As I mentioned in the previous post, domain events stay within a single bounded context, and every bounded context can emit integration events for others to react to.
Coordinating a multi-step workflow like that, where each step depends on the previous one succeeding, needs a dedicated pattern called Saga, to keep data consistent across distributed services even without a single global transaction.
Choreography vs Orchestration
There are two ways to design it:
choreography: where services react to each other’s events with no central coordinator.orchestration: where a central saga instance tells each step what to do next.
I used orchestration here because the order flow has a clear and sequential chain of steps that depend on the previous one being successful, with well-defined compensation logic to handle when any step fails. It keeps everything centralized and visible, instead of scattered across every microservice’s event handlers. However, trade-offs like a single point of failure and the need for resilience must be considered since this doesn’t come for free.
Successful workflow
The successful ordering flow looks like this:
flowchart TB
    OP([OrderPlaced]):::event --> START((Saga<br/>started)):::done
    START --> PO[ProcessOrder]:::cmd
    PO --> OPD([OrderProcessed]):::event
    OPD --> RP[RequestPayment]:::cmd
    RP -.->|async| PF([PaymentFinalized]):::event
    PF --> RCP[RecordPayment]:::cmd
    RCP --> OPA([OrderPaid]):::event
    OPA --> RS[RequestShipment]:::cmd
    RS -.->|async| SF([ShipmentFinalized]):::event
    SF --> RSH[RecordShipment]:::cmd
    RSH -.->|customer confirms| CD[ConfirmDelivery]:::cmd
    CD --> OD([OrderDelivered]):::event
    OD --> DONE((Saga<br/>completed)):::done

    classDef event fill:#f5a623,stroke:#c47f0e,color:#1a1a1a,font-weight:bold
    classDef cmd fill:#7db4de,stroke:#4d8cb8,color:#1a1a1a
    classDef done fill:#e6e6e6,stroke:#9e9e9e,color:#1a1a1a
Compensation workflow
However, there are failure cases you need to predict and compensate for. For example, what if a product sells out between adding it to the cart and placing the order? Or, what happens if a customer exceeds the store credit limit and can’t complete the payment? Or, what if the shipment can’t be delivered because the address is unreachable? These are naive use cases I implemented to demonstrate the mechanism, and not necessarily to reflect real-world ecommerce workflows. A real application may handle these things differently, on top of dozens of other scenarios I’m not even touching here.
With that said, to cover failures, I implemented a compensation flow that looks like this:
flowchart TB

    subgraph COMP[" "]
        direction LR
        PP{{PaymentProcessing}}:::bc -.-> CRL(["CustomerReached<br/>StoreCreditLimit"]):::event --> CA2["CancelOrder<br/>+ restock products"]:::cmd --> OC2([OrderCanceled]):::event
        SP{{ShipmentProcessing}}:::bc -.-> SFail([ShipmentNotDelivered]):::event --> CA3["CancelOrder<br/>+ restock products"]:::cmd --> OC3([OrderCanceled]):::event
        OOS[ProcessOrder]:::cmd -->|product out of stock| CA4[CancelOrder]:::cmd --> OC4([OrderCanceled]):::event
        OCE([OrderCanceled]):::event -->|only if already paid| RCP[RequestCancelPayment]:::cmd --> PC([PaymentCanceled]):::event
        OCE --> DONE((Saga<br/>completed)):::done
    end

    classDef event fill:#f5a623,stroke:#c47f0e,color:#1a1a1a,font-weight:bold
    classDef cmd fill:#7db4de,stroke:#4d8cb8,color:#1a1a1a
    classDef bc fill:#e6e6e6,stroke:#9e9e9e,color:#1a1a1a
    classDef done fill:#e6e6e6,stroke:#9e9e9e,color:#1a1a1a
Hands-on OrderSaga
Let’s look at how the successful and compensation flows above are implemented.
First, the domain events of the order fulfillment workflow (OrderPlaced, OrderProcessed, OrderPaid, OrderDelivered, OrderCanceled) never leave the OrderProcessing bounded context. Apart from the projections, the only one reacting to them is the saga, running in the very same process.
The integration events, PaymentFinalized and ShipmentFinalized on the happy path plus CustomerReachedStoreCreditLimit and ShipmentNotDelivered on failures, are streamed in from other bounded contexts (PaymentProcessing, ShipmentProcessing), whose infrastructure details I’ll cover in the next post.
When a message arrives from another bounded context that OrderProcessing is listening to, that message (or envelope) is deserialized and routed to whichever handler accepts that type in the OrderSaga. Every message carries the OrderId, which Wolverine matches against the saga’s Id to load the right instance.
To implement it, I used Wolverine saga. The OrderSaga partial class follows a simple pattern:
A Start method: it reacts to the first domain event that triggers the entire flow,OrderPlaced, and assigns a unique identifier to the OrderSaga, theOrderId, which is the correlation key that ties every next message in the flow back to the same instance. It then moves the chain forward by returning theProcessOrdercommand, which Wolverine sends on to its handler.Handle methods: the next handle methods in the chain react to incoming domain or integration events, and dispatch the next command, when there is one.
The compensation handlers live in OrderSaga.Compensation.cs, one per failure integration event, plus a handler for OrderCanceled that asks the payment service to cancel the payment when the order was already paid.
💡Update: Like CQRS, OrderSaga used to be a MediatR-based implementation, now replaced by Wolverine’s. It’s way more robust, since the saga state is persisted with Marten, and with a few lines of configuration it gets durable delivery and retries in case of technical failure. I’ll talk more about this in the next post.
Triggering a compensation
There are three failure paths that trigger a compensation:
- Spending more than your store credit limit.
- Shipping to an undeliverable address. This one is a demo simulation in
ProcessShipmentHandler. If theShippingAddresscontains the marker configured underShipmentFailureSimulation:UndeliverableAddressMarkerinappsettings.json(default"308"), the shipment is canceled asUndeliverableandShipmentNotDeliveredis published to theshipmentstopic. - Purchasing more products than are available in stock. There’s no stock reservation, so a product available when added to the cart may be sold out by the time the order is processed.
ProcessOrderHandlerchecks availability while processing the order, and cancels the whole order if anything is short. A more realistic store could prevent that during the purchase, or even handle partial fulfillments, but I kept it all or nothing by design.
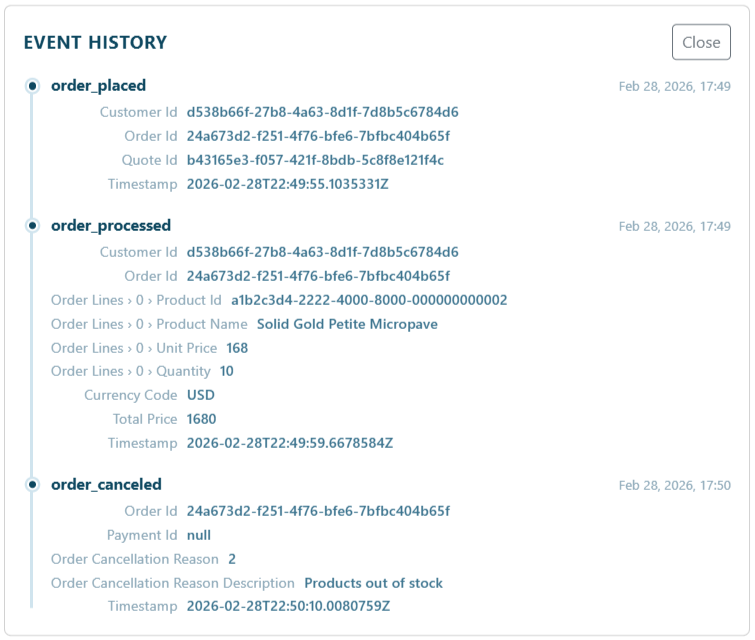
Any of the three results in a canceled order:

A quick check in the events will show exactly the reason:
Final thoughts
In this post, you saw how Marten bridges the gap between PostgreSQL and a fully functional event store, allowing you to write and read domain events without giving up on a familiar relational database infrastructure.
You walked through the IEventStoreRepository abstraction and its Marten-backed implementation, which handles appending uncommitted events and rehydrating aggregates from their event streams. You also saw how inline projections enable live read-model updates, and how EventProjection handles custom event transformations that keep the read side current.
Finally, you saw how the OrderSaga orchestrates the order fulfillment with Wolverine, moving the flow forward on each event and turning every failure into a CancelOrder with a reason and a corresponding compensation action.
The key takeaway is that Event Sourcing is not just about storing events. It’s about structuring your system around the idea that the event history is the truth, and every other representation is derived from it, including the saga reacting to those events to drive the workflow forward.
In the next post of the series, I’ll cover the backend infrastructure, which touches Docker, API gateway, IdentityServer and Kafka. See you there!
Links worth checking
- Aggregates, Events, Repositories with Marten
- EventSourcing.NetCore
- CQRS pattern
- Event Streaming is not Event Sourcing! by Oskar Dudycz
- Optimistic concurrency for pessimistic times
- Domain events
- Ubiquitous language
- Bounded context
- SAGA